The Opportunity: How AI Is Reshaping HRT
The tools that used to belong to the largest chains now sit behind a browser tab. This chapter is about what has actually changed, what has not, and why the operators who win are the ones who learn to ask well rather than the ones who spend most.
The lecture
The Opportunity: How AI Is Reshaping HRT
Lecture video arrives here.
What this chapter argues 1 of 2
The chapter's own argument, distilled. If you read nothing else on this page, read this.
The gap is skill, not access and not money
A boutique hotel can now generate campaign images without booking a photographer. A restaurant group can read fifty thousand reviews overnight and find that the top complaint at one location is one server's attitude on Friday nights. Both of those used to require a budget line and a vendor. Neither does now. What has not been levelled is the knowing what to ask. The same subscription in two hands produces a marketing intern's output in one and a revenue analyst's output in the other, and the difference is not the software. This is the single most useful thing to understand before chapter two, because it tells you where to spend your effort: on the asking, not on the shopping.
Adoption numbers are not results numbers
Eighty-two percent of hotels report expanding their use of AI, and seventy-one percent of hospitality professionals say it is having a significant or transformative impact. Read both carefully. One counts who is using it and the other counts who feels good about using it. Neither counts a change in rate, in cost, or in rating. That is not a reason to dismiss the numbers, and it is a reason to not plan against them. When a vendor quotes adoption at you, the question to ask back is what changed on the profit and loss statement, and how they know it was this. If the answer is a case study with no baseline, you are being sold a feeling.
Four capability areas, and you will use all four
Marketing content covers image and copy generation that fills gaps a photo shoot cannot: off-season imagery, a property mid-renovation, a menu item you added on Tuesday. Data analysis and guest intelligence means uploading a spreadsheet and asking what pattern is in it, which is most of this course. Operations covers forecasting, scheduling, and the written work that eats a manager's week. Personalization covers the guest-facing side, from pre-arrival messages to a response to a bad review that does not read like a template. Most operators start in one and stay there. The compound gain is in using the same working habit across all four.
Most people use AI like a search engine and get a fraction of it
Research on usage patterns puts what most professionals actually capture at ten to twenty percent of what the tools can deliver. Four fixable habits account for almost all of that gap. Vague prompts that give the model nothing to work with. Accepting the first answer when the first answer is a draft. Never giving the model your own data, so it answers about hotels in general instead of about yours. And no verification step, so a wrong number travels straight into a meeting. None of the four requires new software to fix. All four are fixed by chapter three, which is why chapter three is the one the rest of the course leans on.
What this chapter argues 2 of 2
The tools cannot do the part of your job you were hired for
AI is weak exactly where hospitality is hard. It cannot read a room. It has no judgment about a guest complaint that is really about something else. It cannot hold a supplier relationship, sit in a negotiation, or be accountable for a decision. It does not know what your owner will tolerate. Treat that as good news rather than a limitation, because it tells you what to hand over and what to keep. Hand over the reading, the drafting, the counting, and the first pass at any analysis. Keep the deciding. An operator who hands over the deciding gets confident nonsense with their name on it.
It is confidently wrong often enough that verification is part of the job
Hallucination is the term for output that sounds right and is not: invented statistics, citations to papers that do not exist, recommendations built on an assumption the model never mentioned. The trap is that the tone is identical whether the content is correct or fabricated. There is no wobble in the voice to warn you. So verification cannot be a feeling, it has to be a step, and it scales with what is riding on the answer. A caption for a social post needs a glance. A number going into a pricing decision or an owner's report needs a source you can open. Chapter three turns this into a checklist you run every time.
What it costs, in plain numbers
A single operator running this well spends about twenty to forty dollars a month: one paid assistant seat, and often a research tool beside it. That is the whole outlay for most of what this course teaches. Image generation adds a little, and only if you are producing regularly. The free tiers are genuinely usable for learning and they are not enough for the data work, because the file upload and the longer context sit behind the paid tier. Set against one freelance photo shoot or a single month of an analytics subscription, the cost is not the decision. The time to learn the asking is the decision, and that is what you are spending here.
You finish with sixteen things you built, not sixteen things you read
The course runs in four phases and every chapter ends in a deliverable that feeds the next one: a data audit, a KPI scorecard, an analysis portfolio, a visual portfolio, a dashboard, a guest report, a pricing brief, a pitch. By chapter sixteen they add up to a working playbook for your own property rather than a set of notes about someone else's. This is also why the activities ask for your numbers instead of supplying tidy ones. A worked example on invented data teaches you the shape of the method. Your own messy figures teach you the method.
The same twelve reviews, asked two ways
This chapter's claim is that the gap is the asking. Here is that claim performed on a real-shaped set of rows. Nothing changes between the two panels except the sentence typed above the data.
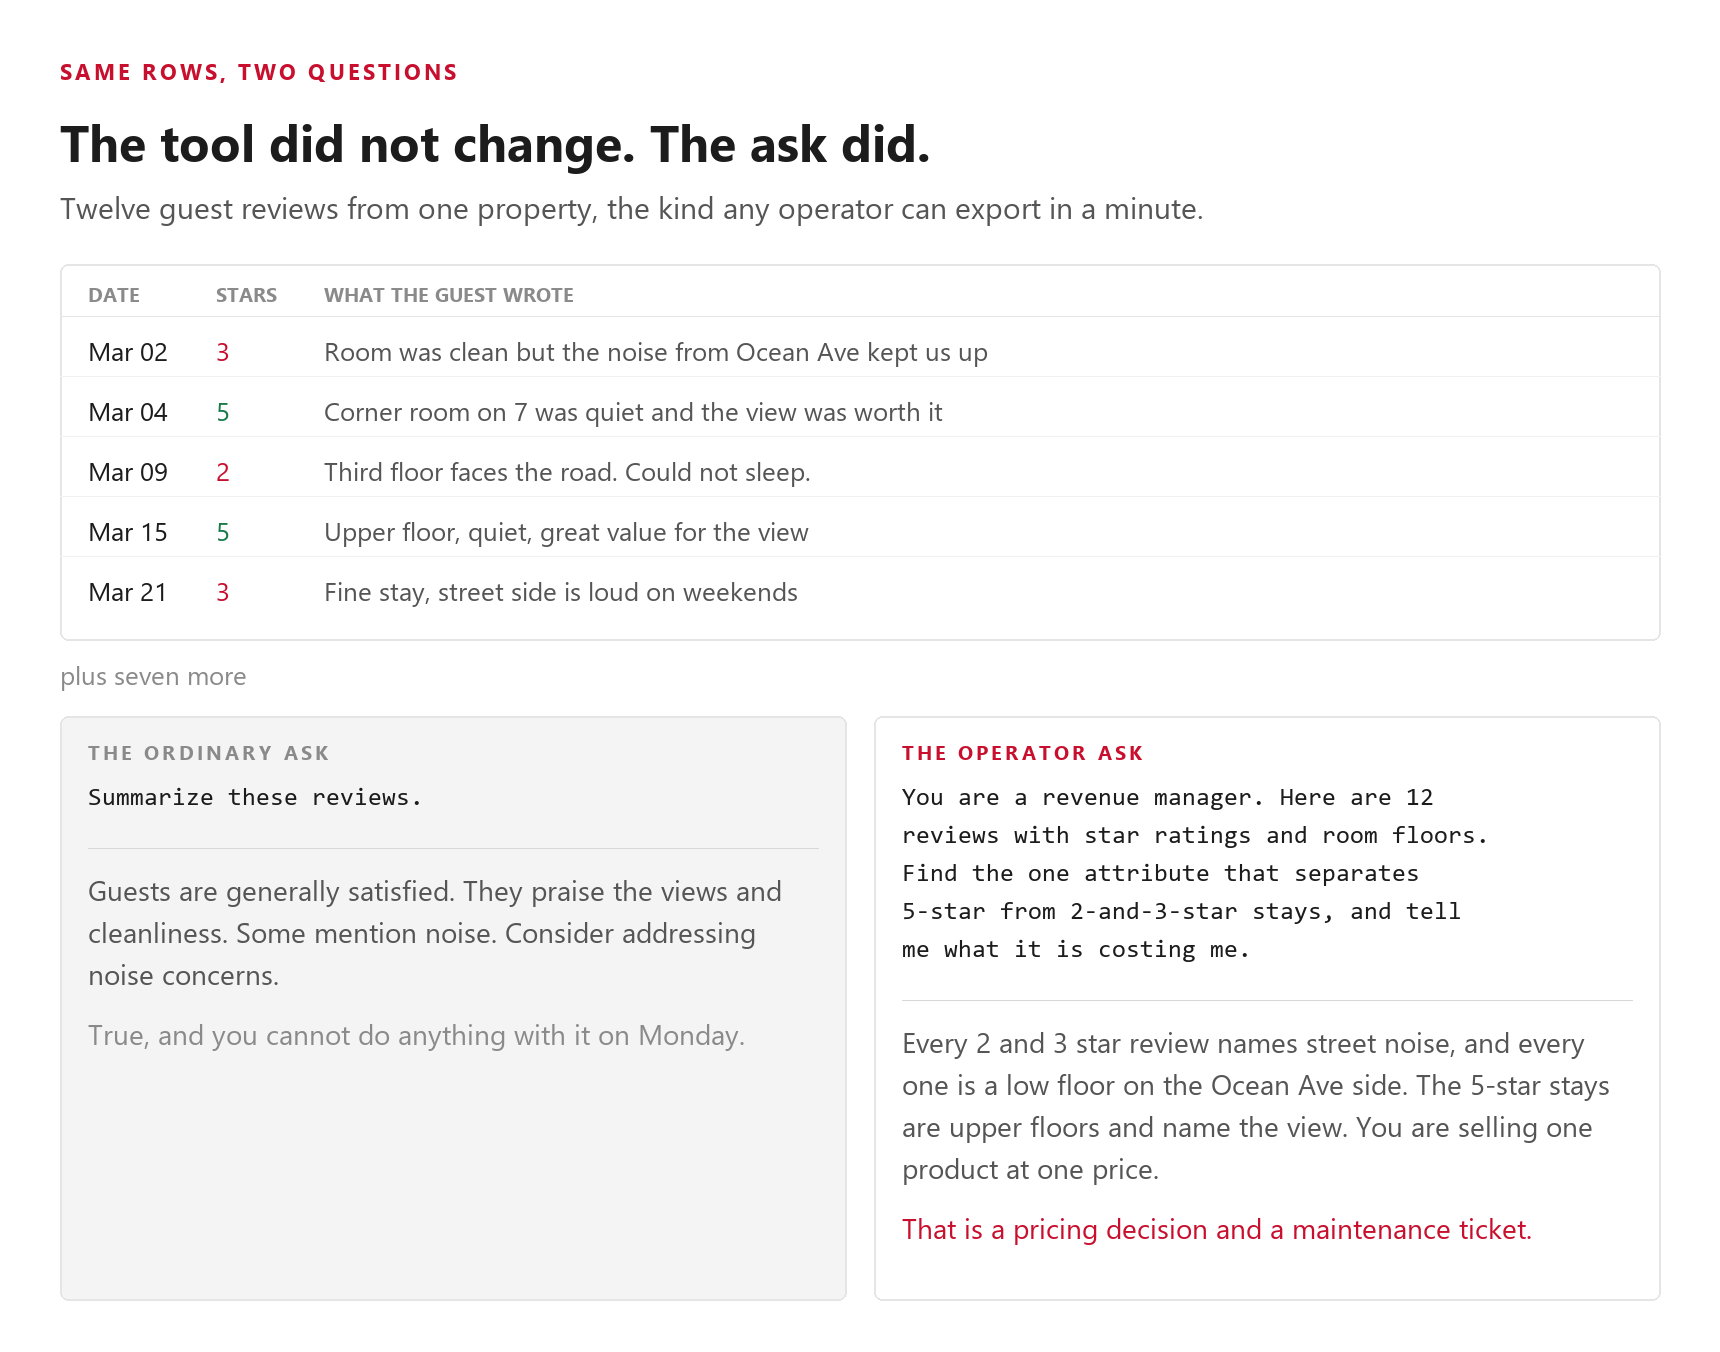
The ordinary ask gets a true answer that changes nothing
Summarize these reviews is a fair request and the reply is not wrong. Guests do praise the view. Some do mention noise. The problem is that every sentence would also be true of a hundred other properties, which means it cannot tell you what to do on Monday. An answer you could have written without reading the data is an answer that did not use the data.
The operator's ask carries three things the first one did not
A role, so the model reasons like a revenue manager rather than a summarizer. The structure of the data, so it knows there are floors and stars to line up against each other. And a specific job with a business consequence attached, which is what turns find the pattern into find the pattern that is costing me money. Those three additions cost one sentence.
The finding is a decision, not a description
Low floors on the road side carry the complaints; upper floors carry the praise and the word view. The property is selling two genuinely different products at one price. That sentence leads somewhere: price the two tiers apart, or fix the windows, and watch the low-floor ratings for eight weeks. The first answer led nowhere at all.
Both panels came from the same tool on the same day with the same twelve rows. If you remember one thing from this chapter, make it this picture: what you get out is set by what you put in above the data, and that part is free.
Score your own AI readiness
No sample answers here: your output, your interpretation, is the exercise.
This chapter's deliverable is an honest baseline across four dimensions: data maturity, AI familiarity, analytical capacity, and skill gaps. Rather than filling in a form alone, hand the AI your real situation and let it interview you into a score. Answer the bracketed parts in plain language; you do not need to sound technical.
Act as a hospitality technology consultant running a short diagnostic interview. I operate a [hotel / restaurant / tour or attraction business] with [size: rooms, seats, or annual visitors] in [city or region].

Here is my honest starting position.
Data maturity: the systems I use are [list every system: PMS, POS, booking platform, review pages, spreadsheets, anything], and I actually look at that data [daily / weekly / monthly / almost never].
AI familiarity: I have used [ChatGPT / Claude / Gemini / none of them] about [how often], for [what tasks, or nothing yet].
Analytical capacity: when I make a big decision about pricing, staffing, or marketing spend, I base it on [intuition / experience / a report I pull / a dashboard], and I currently track performance by [describe it].
Skill gaps: the thing I most wish I could do with data but cannot is [describe it], and the place my business most likely loses money for lack of information is [describe it].

Score me from 1 to 5 on each of the four dimensions, using this scale: 1 means no experience or awareness, 2 means some awareness but minimal practice, 3 means regular but basic engagement, 4 means consistent and purposeful use, 5 means a sophisticated integrated approach. Give me a total out of 20.

Then do three things. First, justify each score in one sentence, quoting the part of my answer that drove it. Second, name the single dimension where improving one point would change my business the most, and say why. Third, list the three obstacles most likely to stop me, based on what I told you, not on generic advice. Be direct. If I scored myself too generously, say so.
Paste it into your own ChatGPT, Claude, or Gemini window and run it. Replace anything in square brackets with your real numbers first.
The search engine test
The chapter argues that the difference between weak and strong output is not the tool but the person using it. The only way to feel that is to run both versions yourself. Open two fresh conversations in the same AI tool so neither one can borrow context from the other.
CONVERSATION ONE. Paste this alone, exactly as written:

What are some ways to improve my hotel's occupancy rate?


CONVERSATION TWO. Open a new chat and paste this, filling in your real numbers:

Act as a revenue management consultant. I run a [size and type] property in [city]. Our average occupancy is [number] percent at an average daily rate of [your ADR in your own currency]. Weekday occupancy, Monday through Wednesday, averages [number] percent while weekends average [number] percent. My competitive set's weekday average is roughly [number] percent.

Analyze that gap and give me five specific strategies to raise weekday occupancy. Rank them by likely impact and by implementation difficulty, and for each one tell me what I would have to do in the first two weeks. Assume I have no marketing agency and no additional budget. Where you are guessing about my market, say so explicitly instead of asserting it.

If you run a restaurant or a tour business, keep the same structure and swap the metrics: covers per day and average check by day part, or bookings and yield per visitor by season.
Paste it into your own ChatGPT, Claude, or Gemini window and run it. Replace anything in square brackets with your real numbers first.
Map the four capabilities onto your week
The chapter names four areas where these tools do real work: marketing content, data analysis and guest intelligence, revenue and pricing, and operational efficiency. Abstractly that is a list. The exercise is to force it onto your actual calendar and see which one is worth your first hour.
I run a [business type and size] in [city or region]. Here is a truthful account of where my working hours go in a normal week: [list five to eight recurring tasks and roughly how long each takes, for example: responding to reviews, building the schedule, writing social posts, checking competitor rates, reconciling the daily sales report].

Sort every one of those tasks into the four categories below, and be willing to say that a task fits none of them.
1. Marketing content: images, copy, and campaign material.
2. Data analysis and guest intelligence: finding patterns in numbers, and reading unstructured text such as reviews.
3. Revenue optimization and pricing: rate and price decisions, demand forecasting, menu or package profitability.
4. Operational efficiency: staffing, purchasing, and routine guest communication.

Then give me a table with one row per task and these columns: Task, Category, Hours per week now, What AI could realistically take over, What must stay human and why, Hours I would likely save.

Finish with a single recommendation: which one task should I automate or assist first, and what is the smallest version of that change I could try this week? Do not recommend buying anything. Assume I have one general purpose AI tool and nothing else.
Paste it into your own ChatGPT, Claude, or Gemini window and run it. Replace anything in square brackets with your real numbers first.
Did the chapter land?
Every answer comes from this chapter. Pick one; a wrong pick tells you where to look and lets you try again.
01Two restaurant groups hold the same paid subscription. One gets answers it acts on; the other gets answers that could describe any restaurant. On this chapter's argument, where is the difference?
02A vendor tells you eighty-two percent of hotels are expanding their use of AI. What has that number established about your property?
03You upload last quarter's costs and ask where to save. The reply recommends renegotiating linen supply, citing an industry benchmark of eleven percent. You have a supplier meeting tomorrow. What comes first?
04Which of these tasks does this chapter say to keep rather than hand over?
05A manager uses AI daily and still gets thin results. Which habit is this chapter most likely to name as the cause?
06You are budgeting for the year. On this chapter's account, what is the realistic monthly software cost for one operator doing this work well?
07Why do this course's activities ask for your own numbers instead of handing you a clean practice file?
The AI Readiness Self-Assessment
An honest baseline you can measure against later. Score yourself now, write the number down with today's date, and keep it: Chapter 16 asks you to take the same assessment again.
Want a read on what you just built?
Send us what you just built.
You now have the ai readiness self-assessment for your own business. Paste it below and we will read it and write back with what we would work on first, and why. No charge and no pitch: if the answer is that you do not need us yet, we will say so.
Goes to Jeong-Yeol Park directly. Nothing is published, and your notes stay on this device unless you press send.